§ 01Introduction
Developers building on web3 networks often ask an AI assistant practical questions, such as how to apply for a grant from a network's funding programme or where to report a security bug in its software. To answer, the assistant reads the network's website on their behalf. If it misses the right page, or repeats one that's out of date, the developer may get a wrong answer presented as fact, and the team behind the network has no way of knowing.
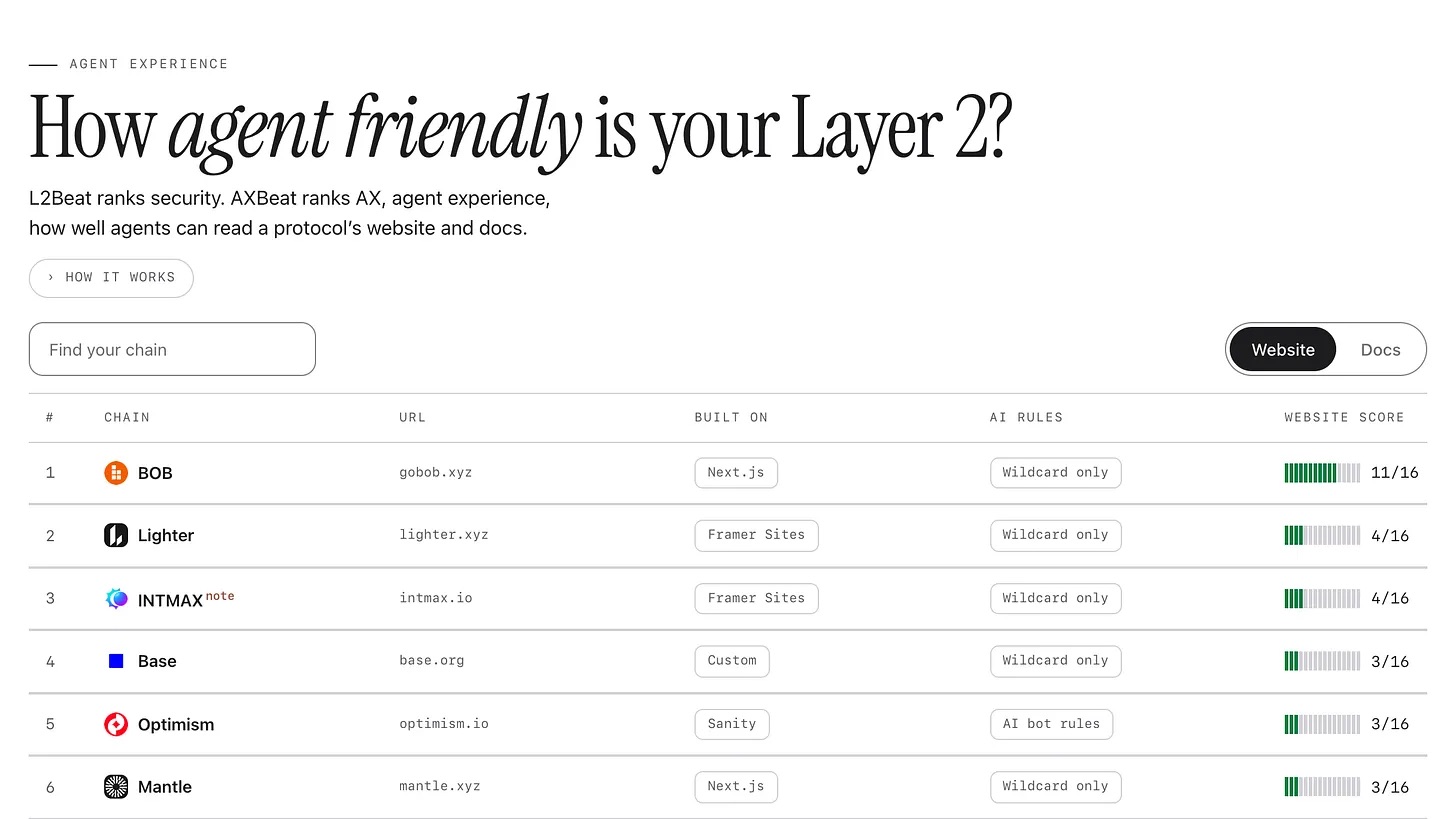
At Mooch, a UX agency and AI product studio in Lisbon, we built AXBeat, a public leaderboard that ranks web3 project websites by how easy they are for AI assistants to read. The scores come from Cloudflare's agent-readiness checks, which look for things like a plain-text version of each page and rules telling AI crawlers what they can read. A leaderboard like this is only worth something if a higher position actually leads to better answers, and nobody had tested that.
To test it, we used AXIS, an open-source test kit for AI assistants built by Netlify. It sends a real AI assistant to a website with a task, records every step it takes and has a second AI grade the result. Like any usability study, it still needs someone to write the questions, the correct answers and the rules for grading them (together, the answer keys). That was my role as the researcher on both studies. In the second, I also made the final call on any mark that was in doubt.
§ 02User needs
I want an AI assistant to give me the correct answer from the project's own website
so that I can apply for funding, report a bug or get in touch without checking every claim myself
§ 03Research approach
One AI answered, a second AI graded, and I checked every mark
In both studies the assistant was Claude Sonnet 5.5, Anthropic's latest frontier model for everyday tasks, running in Claude Code, Anthropic's coding tool. It started fresh every run, with no memory and none of our files or settings.
The grader was Claude Fable 5, Anthropic's most capable model, because grading a full transcript against a key requires a lot of judgement. It read the assistant's whole transcript, every step it took, and marked each answer against my keys. We also checked every mark by hand rather than trusting the grader, because an AI grader can mark near-identical answers differently.
The keys: what counted as a correct answer
For every question I wrote what counted as correct, partly correct and incorrect, and which page the answer had to come from. For study 2, I also checked each answer on the live site myself before any runs.
One rule ran through every key: anything false makes the answer incorrect, even if the rest is correct, and a partly correct answer has to be sourced and contain nothing false. An answer with no page from the site behind it counts as not found, because it likely came from the model's memory rather than the website itself.
Study 1: two sites, top and bottom of the leaderboard
We picked one site that scored highly on AXBeat and one that scored low. I wrote three questions a developer might ask, about getting funding, reporting a security bug and finding a partnerships contact, and the correct answer to each for both sites.
The assistant answered every question on both sites six times over: once in a trial round to check the system was working, then five times that counted. Three questions, two sites, six answers each: 36 graded runs, where a run is one complete attempt at one question.
Hypothesis: the assistant would answer correctly more often on the site with the higher score.
Study 2: one site, one change
For the second study we tested two versions of one site, keeping the content constant. We copied the website of one of the five largest networks on the leaderboard, privately, and made two versions of it. Version A served its pages as normal code (HTML), the way websites usually do. Version B was identical, except it also served a plain-text (markdown) version of every page to assistants that ask for one, which is the change AXBeat's checks look for.
I wrote five questions, each answered on a different page of the site, and each turning on a detail that appears only on that page, so the assistant had to find the page rather than answer from memory. The assistant answered each of the five questions ten times on each version: 100 graded runs. We disabled web search, so the assistant had to use the site, and the site's own records of each visit confirmed that version B served plain text on all 50 of its runs and version A served normal HTML on all 50.
Hypothesis: assistants reading version B, with the plain text Cloudflare's agent-readiness checks recommend, would return more correct answers, and do so faster and cheaper.
<nav class="site-nav">…</nav>
<div class="hero-banner">
  <h1>Grants</h1>
  <img src="hero.svg">
</div>
<p>Apply by 30 June with
a one-page proposal.</p>
<ul class="card-grid">
  <li>Up to $50k</li>
  <li>Open to any team</li>
</ul>
<footer>…</footer>
# Grants

Apply by 30 June with
a one-page proposal.

- Up to $50k
- Open to any team
Limitations
Both studies are small and specific. Study 1 compared a single pair of sites, and study 2 covered one site, five questions and one AI assistant, so the results hold for that setup rather than for every site or every assistant.
My answer keys are also only as complete as my own checks. I confirmed each answer on the page it came from, but I didn't read every single page of each site, so a site could hold another valid answer, or one that contradicts mine, that my key missed. This happened once in study 1, when the assistant found two contact routes in the top site's docs that my partnerships key didn't include.
§ 04Findings
Study 1: the low scorer gave better answers
The site at the bottom of the leaderboard gave better answers.
Contrary to our hypothesis, the low-scoring site answered slightly better: 10 correct answers out of 15 against the high-scoring site's 9, and no incorrect answers, while the high-scoring site gave 3.
The content decided the answer
Where the assistant's answers deviated from the key, the content was the cause. The website's funding page wasn't linked from the main site or the docs menu, and an assistant navigating a site finds pages the way people do, by following links, so an unlinked page may as well not exist.
An old blog post also still invited projects to apply to a funding programme that closed in July 2025. In 3 of the 5 funding runs the assistant passed that post on as a live way to apply, which made the high scorer the only site where it stated something false as fact.
Assistants search first
In 34 of the 36 runs the assistant started with a web search rather than the site's own navigation, so for study 2 we disabled search to make sure it was just the website being tested.
Study 2: near-perfect answers on both versions
Same answers, a third less reading.
Our hypothesis was only partly right. Version B scored 100%: all 50 answers correct. But version A scored almost as highly, 49 correct and 1 partly correct, so the plain-text version had almost no room to show a gain in accuracy. The one partly correct answer named everything the question asked for, then second-guessed itself.
How a page reaches the assistant
The plain text did make a difference, just not to the answers. To see where, it helps to know how Claude Code handles a page. It doesn't hand a fetched page straight to the main assistant. A smaller model, which we call the page reader, reads the page first and passes on a summary.
Version B cut the reading by a third
On version B the page reader processed 34% fewer tokens, the units of text an AI model reads and is billed for, somewhere between 30% and 37% fewer across repeat runs. Every one of the five questions showed the saving, from 27% to 43%. Across the whole run, it came to 8% fewer tokens.
No change in cost or time
Because the main assistant only sees the page reader's summary, and summaries are usually around the same size, the number of tokens it spent barely varied between A and B. Neither did the cost or the time: a run cost about four US cents on either version. So the faster and cheaper half of our hypothesis didn't hold.
§ 05Recommendations
For web3 teams who want AI assistants to answer questions about their project correctly:
Fix the content first. A site can score top marks for agent readiness and still give wrong answers, because checks like AXBeat's, or Cloudflare's behind it, measure whether an assistant can read your site, not whether what it reads is true. In study 1, the site at the top of the leaderboard was the only one where the assistant stated something false as fact, because an old post still advertised a funding programme that had closed. Make sure every answer people need sits on a current page your site links to, and update or retire posts about programmes that have closed.
Serve a plain-text version for the right reason. It's a small change that cut what the assistant had to read by about a third, but on a site that was already readable it didn't change the answers, so treat it as tidying rather than a fix for accuracy.
Test changes on your own site. If you compare your site with another project's, the two will differ in content, layout and how up to date they are, so you can't tell which of those caused a difference in the answers. Ask an assistant the same questions before and after you make one change, and any difference will come from that change.
§ 06Deliverables
Everything the studies produced, reusable for the next test.
§ 07Impact
- Study 1 changed how we test. Comparing two sites gave way to before and after tests on one site, the shape study 2 used and the next test will use.
- Together, the studies give us honest advice for web3 teams: content decides whether the answer is correct, and a plain-text version mostly trims what the assistant reads.
- The recommended next test looks at a site that blocks AI assistants, where a single change can decide whether the assistant gets an answer at all.
§ 08Reflections
What worked well. Hand-checking every mark. In study 1 the grader marked near-identical answers correct in the trial round and partly correct in the round that counted, and in study 2 it gave one answer a mark outside the scale, which I ruled partly correct. It also helped that each question needed a detail only found on the site's own page, such as the number of support hours in the first year, so the assistant couldn't score by answering from memory.
What I'd do differently. In study 1 I'd check by hand, before writing the questions, that each answer was on the site, up to date and linked from the main pages. An unlinked page and a stale post cost the top site marks, a useful finding that nevertheless muddied the comparison, so in study 2 I checked every answer on the live site first. We'd also have the grader mark from the assistant's transcript alone from the start, since grading made up 95% of study 2's spend.
What I learned. The rule I follow with people, change one thing at a time so you know what caused a shift in behaviour, holds just as well when the user is an AI assistant. An assistant that can read a site perfectly will still repeat whatever the site says, current or not.
What this means for AXBeat. The leaderboard measures whether an AI assistant can get into a site and read it, which matters, because an assistant that's blocked can't give any answer at all. What it can't measure is whether the content is correct and up to date, and once the assistant is in, that's what decides the answer. A good score is a starting point rather than a guarantee.
If you'd like to know whether AI assistants give your users the correct answers about your project, I can help you plan and run the test. Email me →